json-tokenize 


Splits a JSON string into an annotated list of tokens.
- Keeps track of a tokens position
- Whitespace significant
- Doesn't validate the correctness of the syntax
Screenshot - formatted tokens outputted to stdout
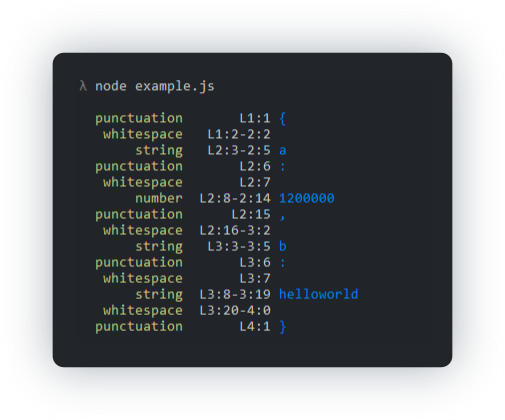
View Example
Installation
npm install --save json-tokenize
Or even better
yarn add json-tokenize
Import and Usage Example
const tokenize = require('json-tokenize')

const obj = { "test": 1.0 }

tokenize(JSON.stringify(obj))
// ->
[
  { type: 'punctuation',
    position: { lineno: 1, column: 1 },
    raw: '{',
    value: '{' },
  { type: 'whitespace',
    position: { start: [Object], end: [Object] },
    raw: '\n  ',
    value: '\n  ' },
  { type: 'string',
    position: { start: [Object], end: [Object] },
Tokens
- whitespace - Allowed white space between the actual relevant tokens.
- punctuator - The characters sorrounding your data:
{, }, [, ], : and ,
- string - JSON String
- number - JSON Number
- literal -
true, false or null
Author
json-tokenize © Fabian Eichenberger, Released under the MIT License.
Authored and maintained by Fabian Eichenberger with help from contributors (list).
GitHub @queckezz · Twitter @queckezz